Products — AI Server

On-premise AI compute.Your data never leaves your facility.

Five configurations, M1 to M5, from departmental inference to sovereign AI data centers. Your process data, customer records, and proprietary models stay inside your facility, never on someone else’s cloud. It is a one-time capital cost, predictable from day one, not an open-ended cloud bill. Built on NVIDIA, Intel, and Supermicro.

  • Data stays on-site
  • Payback typically ~12 months
  • No open-ended cloud bill
  • NVIDIA · Intel · Supermicro
  • No GPU waitlist
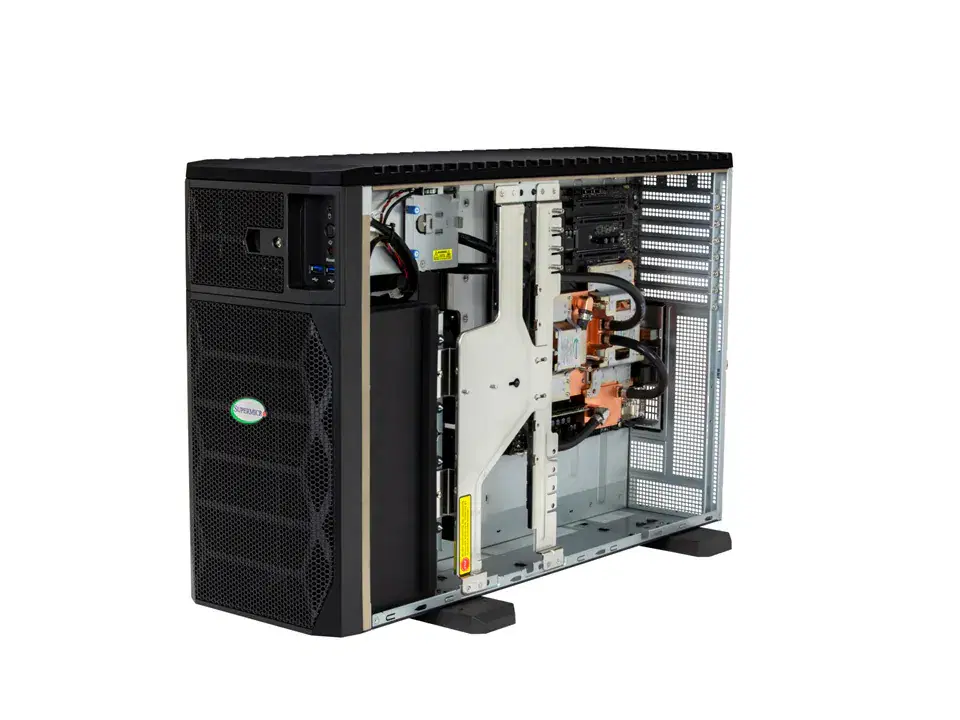
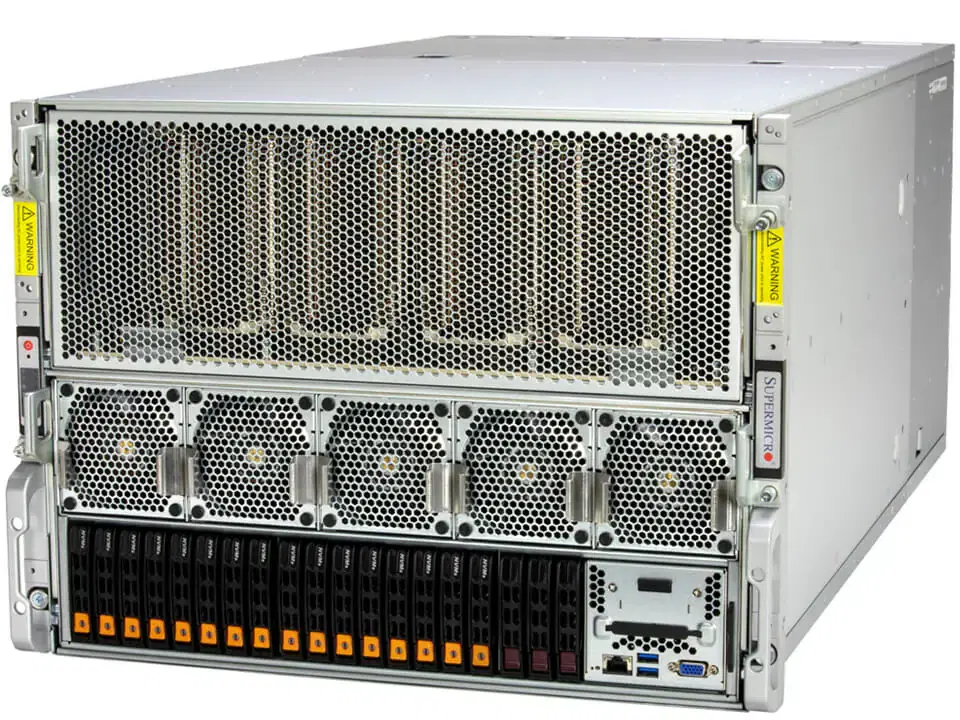
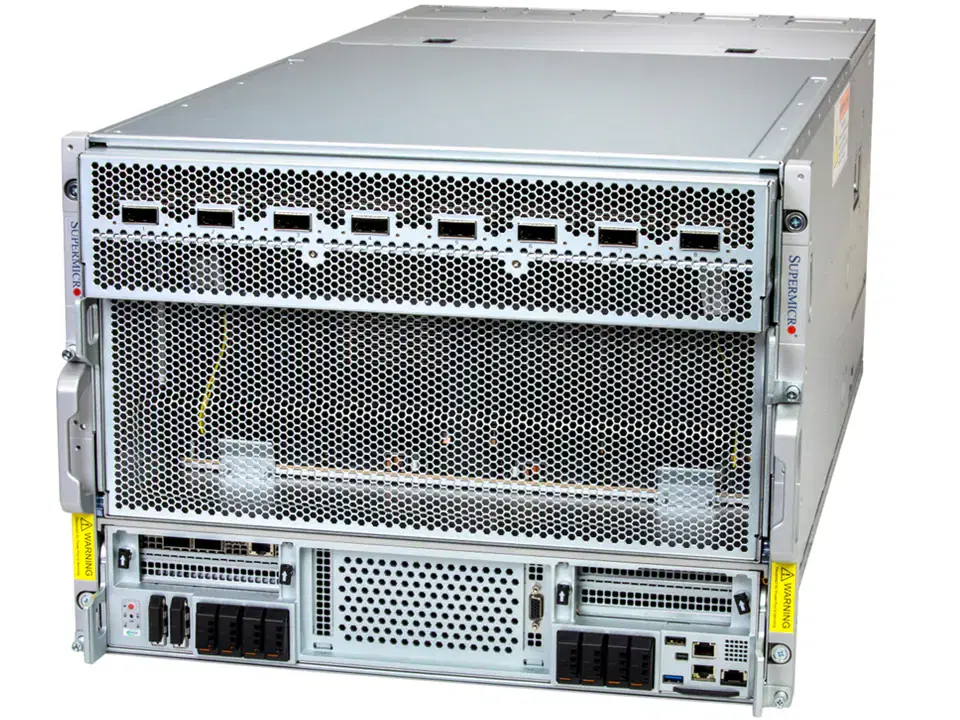
MICH AI Server — high-density GPU servers

01

Why On-Premise

Your data leaves your facility

Cloud inference means your process parameters, customer records, and proprietary models are processed on someone else’s servers. In manufacturing, healthcare, government, and finance, that is a compliance exposure, not a preference. On-premise, your data never leaves the building.
Cloud costs scale with usage

Cloud inference charges per token. As AI workloads expand across your operation, costs accumulate linearly with no ceiling. On-premise hardware is a one-time capital decision with predictable costs from day one, and payback typically lands at ~12 months (9–14), based on a customer pilot and internal estimate.

Supply chain you can trace

Every MICH configuration is built on genuine NVIDIA, Intel, and Supermicro hardware through standard channels, with sourcing traceable at the component level and no modified or gray-market parts.

02

Who This Is For

Factory IT & Operations

Manufacturing

ERP, MES, and shop-floor data that cannot leave the facility. AI that needs to run when the network goes down. Procurement that requires supply chain origin documentation.

Healthcare, Government, Finance

Compliance-Sensitive

Regulated industries where data sovereignty is a legal requirement. Environments that must operate fully air-gapped. Procurement that requires verified, traceable hardware origin.

Sovereign Compute

Enterprise AI

Organizations building private AI data centers. Teams deploying 100B+ models on-premise. Any operation that needs compute infrastructure that answers only to them.

Included with every configuration LowsiteOS connects your ERP, MES, and IoT data and turns it into on-site, queryable intelligence. No cloud API. No data leaving your facility.

Learn about LowsiteOS

03

Configurations

M1–M2

Start · one team

Piloting AI, or running it for a single team? One deployable unit for the office, clinic, or lab. No server room, no facility modification.

M2–M3

A whole department

Multiple models in parallel, or a 120B+ model on a single box. Slots into your existing 5–7kW rack, with no construction and no waiting.

M4–M5

Organization-wide & sovereign

A private AI data center serving 200–500 users, or frontier-model training at national scale. Compute that answers only to you.

M1Departmental · Edge

Starter

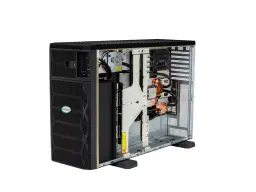
Edge Silent Workstation

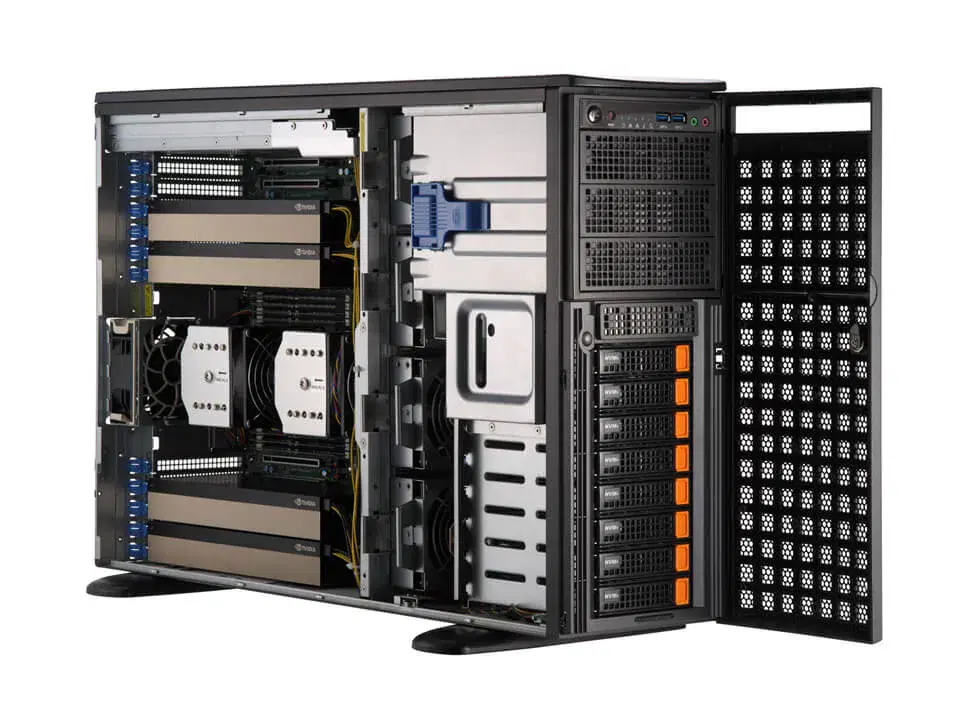
Supermicro SYS-741GE-TNRT (4U Tower · 28dB)

Best for

Your engineers run models next to the workstation. Data never leaves the floor. Within 90 days you know whether this AI direction is worth scaling.

Hardware
Supermicro SYS-741GE-TNRT (4U Tower · 28dB)
GPU
NVIDIA RTX PRO 6000 Blackwell ×1–2
VRAM
96–192GB GDDR7 ECC
System Memory
DDR5 5600 up to 4TB

What you can run

RAG knowledge base, natural-language BI, speech AI (Riva), and vision / medical-imaging pilots (Metropolis, Clara). Open models up to 70B, or 120B on the 192GB config.

M2Multi-model · Rack

Department

Enterprise High-Density Rack

Supermicro SYS-422GL-FNR2 (4U Rackmount)

Best for

Multiple AI models running in parallel, across departments. Slots into your existing 5–7kW rack infrastructure, with no facility upgrade and no waiting on construction.

Hardware
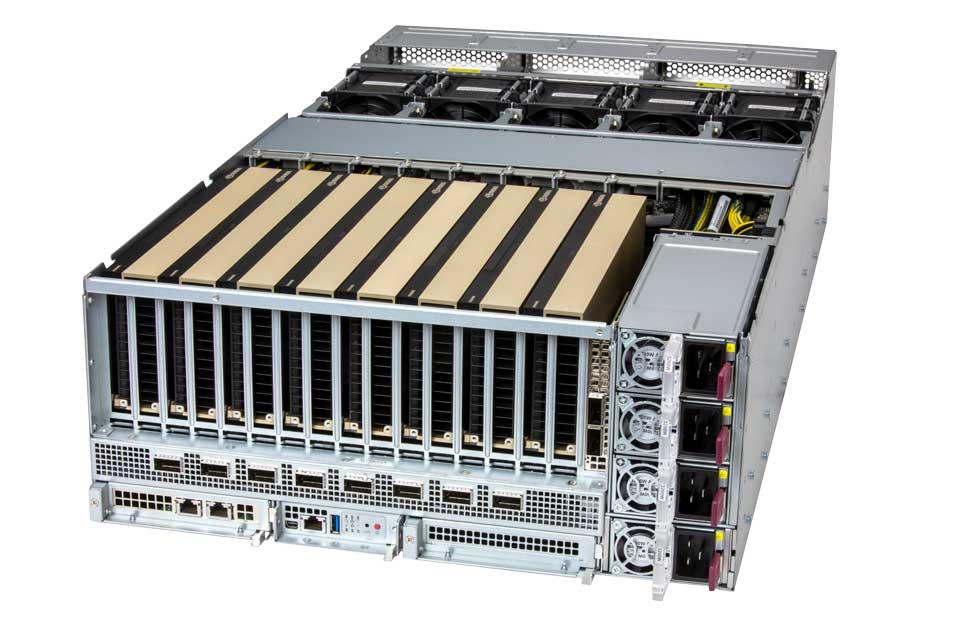
Supermicro SYS-422GL-FNR2 (4U Rackmount)
GPU
NVIDIA RTX PRO 6000 Blackwell ×8 (PCIe · CX-8 switch)
VRAM
768GB GDDR7 ECC (96GB×8)
System Memory
DDR5-6400 up to 6TB

What you can run

Several production models at once: contact-center speech (Riva), scheduling optimization (cuOpt), real-time security (Morpheus), and org-wide RAG, all from one rack.

M3All-in-One · Liquid Cooled

Research

All-in-One Flagship Node

Supermicro ARS-511GD-NB-LCC (5U AI Station · Liquid-Cooled)

Best for

Running 120B+ frontier models on a single unit without VRAM bottlenecks. Deploys desk-side or in a lab, with no raised floor and no specialized cooling infrastructure.

Hardware
Supermicro ARS-511GD-NB-LCC (5U AI Station · Liquid-Cooled)
GPU
NVIDIA GB300 Grace Blackwell Ultra (Grace 72C + B300)
Unified Memory
748GB coherent (HBM3e + LPDDR5x)
System Memory
496GB LPDDR5x SOCAMM (in coherent pool)

What you can run

120B+ frontier LLMs unsplit in 748GB coherent memory, plus Omniverse digital twins, BioNeMo / Parabricks genomics, and Modulus yield RCA, all on one box.

M4Enterprise AIDC

AIDC

FSI-Grade Production Core

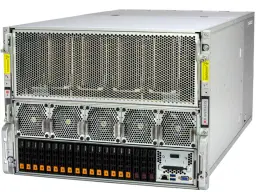
Supermicro SYS-821GE-TNHR (8U Rackmount)

Best for

Organizations that need a private AI data center: serving 200–500 concurrent users, running multiple large models, with compute sovereignty that no vendor or government can interrupt.

Hardware
Supermicro SYS-821GE-TNHR (8U Rackmount)
GPU
NVIDIA HGX H100/H200 8-GPU (SXM5 · NVLink)
VRAM
1,128GB HBM3e (141GB×8)
System Memory
DDR5 5600 up to 8TB

What you can run

Multi-tenant production for 200–500 users: org-wide RAG, real-time fraud / AML (Morpheus), speech at scale, and NeMo fine-tuning, each department isolated in its own lane.

M5Sovereign AI

AIDC Pro

Sovereign Compute Core

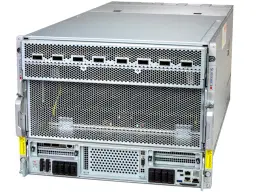
Supermicro SYS-822GS-NB3RT (8U · Xeon 6 DP)

Best for

National-scale AI deployments, 100B–1T+ model training, and sovereign compute infrastructure. For organizations where the compute itself is a strategic asset, not a service rented from someone else.

Hardware
Supermicro SYS-822GS-NB3RT (8U · Xeon 6 DP)
GPU
NVIDIA HGX B300 8-GPU (NVLink 5 · 1.8TB/s) · Air-Cooled
VRAM
2.3TB HBM3e (288GB×8)
System Memory
DDR5 RDIMM up to 8TB

What you can run

100B–1T+ model training (NeMo), multi-node clustering over 800GbE, multi-site Omniverse collaboration, and Earth-2 climate / disaster simulation, all at sovereign scale.

Specs

M1–M5 full specification comparison

All tiers share the same LowsiteOS operating layer. ★ = Phase 1 recommended.

TierGPUVRAM / MemoryPositioningLead (MICH)
Workstation· Desk-side · department deploymentM1 · M3
Supermicro SYS-741GE-TNRT (4U Tower · 28dB)
M1
Starter
Supermicro SYS-741GE-TNRT (4U Tower · 28dB)
Datasheet PDF
NVIDIA RTX PRO 6000 Blackwell ×1–2
96–192GB GDDR7 ECC
DDR5 5600 up to 4TB
Edge PoC / dev teams · 28dB desk-side⚡ 1.5wvs 3w direct
Supermicro ARS-511GD-NB-LCC (5U AI Station · Liquid-Cooled)
M3Pick
Research
Supermicro ARS-511GD-NB-LCC (5U AI Station · Liquid-Cooled)
Datasheet PDF
NVIDIA GB300 Grace Blackwell Ultra (Grace 72C + B300)
748GB coherent (HBM3e + LPDDR5x)
496GB LPDDR5x SOCAMM (in coherent pool)
R&D core · 748GB coherent memory, one box · 28dB⚡ 2.5wvs 6w direct
Rack· Data-center · AIDC deploymentM2 · M4 · M5
Supermicro SYS-422GL-FNR2 (4U Rackmount)
M2Pick
Department
Supermicro SYS-422GL-FNR2 (4U Rackmount)
Datasheet PDF
NVIDIA RTX PRO 6000 Blackwell ×8 (PCIe · CX-8 switch)
768GB GDDR7 ECC (96GB×8)
DDR5-6400 up to 6TB
Departmental inference pool · fits 5–7kW legacy racks⚡ 2wvs 4w direct
Supermicro SYS-821GE-TNHR (8U Rackmount)
M4
AIDC
Supermicro SYS-821GE-TNHR (8U Rackmount)
Datasheet PDF
NVIDIA HGX H100/H200 8-GPU (SXM5 · NVLink)
1,128GB HBM3e (141GB×8)
DDR5 5600 up to 8TB
AIDC core · multi-tenant serving · under a 15kW rack⚡ 4wvs 9w direct
Supermicro SYS-822GS-NB3RT (8U · Xeon 6 DP)
M5Pick
AIDC Pro
Supermicro SYS-822GS-NB3RT (8U · Xeon 6 DP)
Datasheet PDF
NVIDIA HGX B300 8-GPU (NVLink 5 · 1.8TB/s) · Air-Cooled
2.3TB HBM3e (288GB×8)
DDR5 RDIMM up to 8TB
Sovereign AI / national scale · 100B–1T+ training & multi-modal R&D⚡ 5wvs 12w direct
★ Phase 1 recommended. Lead time is the fastest reference via the MICH Taiwan supply chain.

Solutions

What each tier does for you

Every AI Server ships with its matching LowsiteOS solution tier (T1–T5). Pick a tier to see its built-in features, sellable scenarios and industry use cases.

M1 · Edge Silent Workstation◆ LowsiteOS T1 Starter

Plug in, and start.

Your first on-prem AI machine. Ask your data questions in plain language, auto-build dashboards, stand up a company knowledge base, deploy AI agents, all with no team to hire and no code to write. Runs open models up to 70B (gpt-oss-120B on the 192GB config).

28dB
Desk-side quiet, no server room
70B
Open models out of the box
Day 1
Company knowledge base live
Supermicro SYS-741GE-TNRT (4U Tower · 28dB)
96–192GB GDDR7 ECC
Who it's for
Teams adopting on-prem AI for the first time
  • Algorithm developers & research labs
  • Department pilots — start on a team budget
  • No server room needed: fits the office, clinic, or lab

Scenarios you can put live

· Mapped to NVIDIA AI Enterprise
Analytics + BI (Gen BI natural-language query)
Knowledge Base RAG (KM Master)
Speech AI (Riva ASR/TTS · live translation)
Medical-imaging prototyping (Clara/MONAI)
Drug-discovery PoC (BioNeMo NIM)
Industrial vision AI pilot (Metropolis)

💡 What it looks like in your industry

Run BioNeMo protein-structure & docking PoCs in your own lab, where data never leaves the building. First results in weeks, then decide whether to scale.
※ The entry point for all six verticals

LowsiteOS features included
Full LowsiteOS suite, out of the box:
  • ① Data Hub — source connectors · Data Factory · Data Dictionary
  • ② Analytics & BI — natural-language query, auto analysis, insights & recommendations, drag-and-drop dashboards
  • ③ AutoML & Scheduling — no-code model training, evaluation / explanation / testing
  • ④ Knowledge Base (RAG) — document upload, OCR parsing, vector retrieval QA
  • ⑤ LowsiteOS AI — LLM Registry, agent configuration, MCP, Enterprise GPT

04TCO Advisor

Not sure which tier fits?

Don’t guess. The Spec Advisor recommends the right M-tier for your workload and scale, then estimates your 3-year TCO against equivalent cloud spend.

Free · instant · no signup

05Trusted Hardware & Local Delivery

Genuine hardware. Delivered locally.

Every MICH AI Server is built from 100% genuine, standard-channel NVIDIA, Intel, and Supermicro hardware with full manufacturer warranty. It is integrated and delivered locally, with predictable lead times and on-site support.

Standard channel

Genuine Hardware

NVIDIA · Intel · Supermicro

100% genuine, first-tier components, with no modified or white-box parts. Serial-traceable, with full manufacturer warranty.

Integrated in Taiwan

Local Delivery

Single point of contact

Integrated and shipped locally, with transparent, predictable lead times. MICH holds stock of common configurations, skipping the OEM build and GPU-allocation queue for a noticeably shorter wait.

Local engineers

On-site Support

Install · warranty · maintenance

On-site installation and training, warranty, maintenance, and remote monitoring. When something needs attention, someone shows up.

06FAQ

What buyers ask before they decide.

The questions we hear most, on cost, data, lead time, and getting started.

Cost & ROI

Data, Security & Deployment

Hardware, Lead Time & Support

Choosing & Getting Started

Book a Demo

Know which configuration you need?

Tell us about your facility and workload. We’ll respond promptly with a configuration recommendation specific to your environment. Prompt response · No commitment

Fast response · Free consultation

Book a Demo